Meta Defeats Authors in AI Training Lawsuit, but Legal Debate Continues

Meta Defeats Authors in AI Training Lawsuit, but Legal Debate Continues
A federal judge dismisses authors' copyright claims against Meta, ruling the company legally trained its AI models.
After a U.S. federal judge ruled against a group of authors who claimed that Meta Platforms illegally used their books to train its artificial intelligence models, the company has won a high-stakes copyright case. The U.S. District Court in San Francisco's Judge Vince Chhabria dismissed the authors' claims on Wednesday, stating that there was not enough proof that Meta's AI system, Llama, violated their copyrights under current U.S. law.
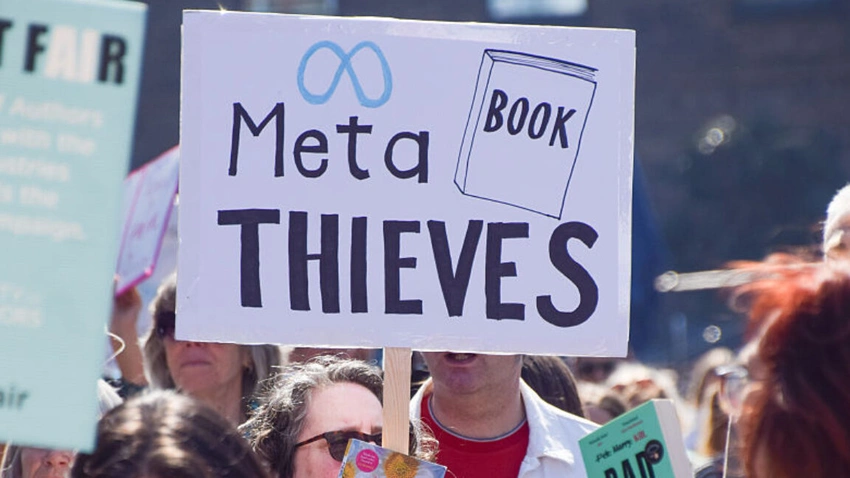
The lawsuit, which was filed in 2023, claimed that Meta had trained Llama using pirated copies of the authors' works without their consent or payment. The case is one of several that writers, news outlets, and copyright holders have filed against big tech firms like Microsoft, OpenAI, and Anthropic, questioning whether the common practice of using copyrighted content for AI training qualifies as "fair use" under US law. Meta Is Not a Clean Slate. Judge Chhabria quickly clarified that the decision, even though it favored Meta, did not support the company's practices.
“This ruling does not stand for the proposition that Meta's use of copyrighted materials to train its language models is lawful,” Chhabria wrote. “It stands only for the proposition that these plaintiffs made the wrong arguments and failed to develop a record in support of the right one.”
According to Chhabria, a crucial component of a successful copyright infringement claim is the authors' demonstration of how Meta's use of their books would hurt the market for their original works. He did, however, voice concerns about the possible negative effects on the economy and creativity of permitting generative AI tools to be trained on copyrighted material without permission.
Judges Differ on Fair Use of AI Chhabria's view differs from another decision made earlier this week by U.S. District Judge William Alsup, who is based in San Francisco, who determined that Anthropic's use of copyrighted content qualified as "fair use" in a case involving the AI company.
The legal ambiguity surrounding AI training practices is highlighted by this widening gap between judicial interpretations. The stakes are also raised for current and upcoming cases, such as a number involving OpenAI and its GPT models, which significantly rely on enormous amounts of internet data, including copyrighted material.
A Meta representative praised the ruling and defended the fair use framework in a statement, calling it "essential for developing transformative AI technology." However, the authors' legal team strongly objected to the decision. Using what they described as an "undisputed record" of Meta's "historically unprecedented pirating of copyrighted works," a representative for the plaintiffs' legal firm, Boies Schiller Flexner, stated that they disagreed with the judge's decision.
The Creative Disruption of AI: A Judicial Concern. Judge Chhabria expressed concern about the wider ramifications of AI training, even though Meta won. He recognized the authors' worries that generative AI might seriously threaten established creative industries both in the May hearing and in Wednesday's decision.
According to Chhabria,“By training generative AI models with copyrighted works, companies are creating something that often will dramatically undermine the market for those works, and thus dramatically undermine the incentive for human beings to create things the old-fashioned way.”
His comments imply that although Meta avoided this specific difficulty, legal scrutiny of AI training methods is still ongoing.
