Musk Admits Distilling OpenAI Data for xAI, Sparking Controversy
Musk Admits Distilling OpenAI Data for xAI, Sparking Controversy
Elon Musk testifies that xAI distills OpenAI data to train Grok, a move critics call risky and anti-competitive as rivals weigh in on AI dominance and data rights.
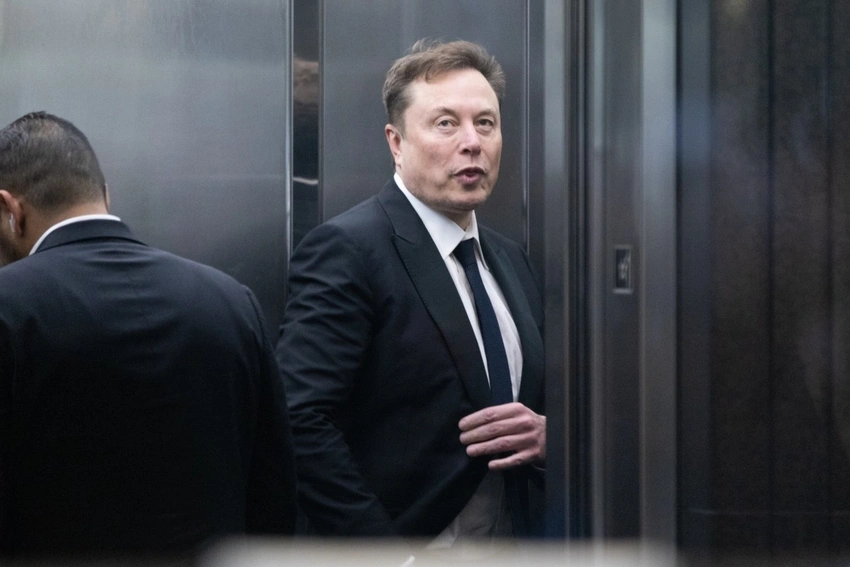
In testimony under oath this week, Elon Musk revealed that xAI has been distilling data from OpenAI to train its Grok system. The admission underscores a hot topic in the AI world: how much access to a rival's data is permissible to build better models, and where the line should be drawn between competition and copyright.
Musk framed distillation as a standard practice among frontier labs, arguing that using competitors' models to understand capabilities helps push the field forward. He pointed to Grok as a concrete example of a model shaped, in part, by OpenAI's work.
Critics warn that this approach can amount to data poaching, potentially exposing proprietary training data to re-creation by others. They call for clearer licensing rules and stronger safeguards to prevent theft of training data.
Conversely, proponents say distillation accelerates innovation and keeps the industry moving. The debate is complicated by public accusations that rivals like Anthropic may have used data obtained without permission, raising the stakes for regulatory scrutiny.
The controversy comes as investors and policymakers watch closely how AI labs source data and train new models. Analysts say the outcome could influence licensing norms and the competitiveness of smaller players in a fast-evolving market.
As the industry pushes forward, the central question remains: how can companies balance rapid advancement with fair use, proper attribution, and respect for proprietary data? The discussions are likely to intensify as more labs weigh similar strategies.
